
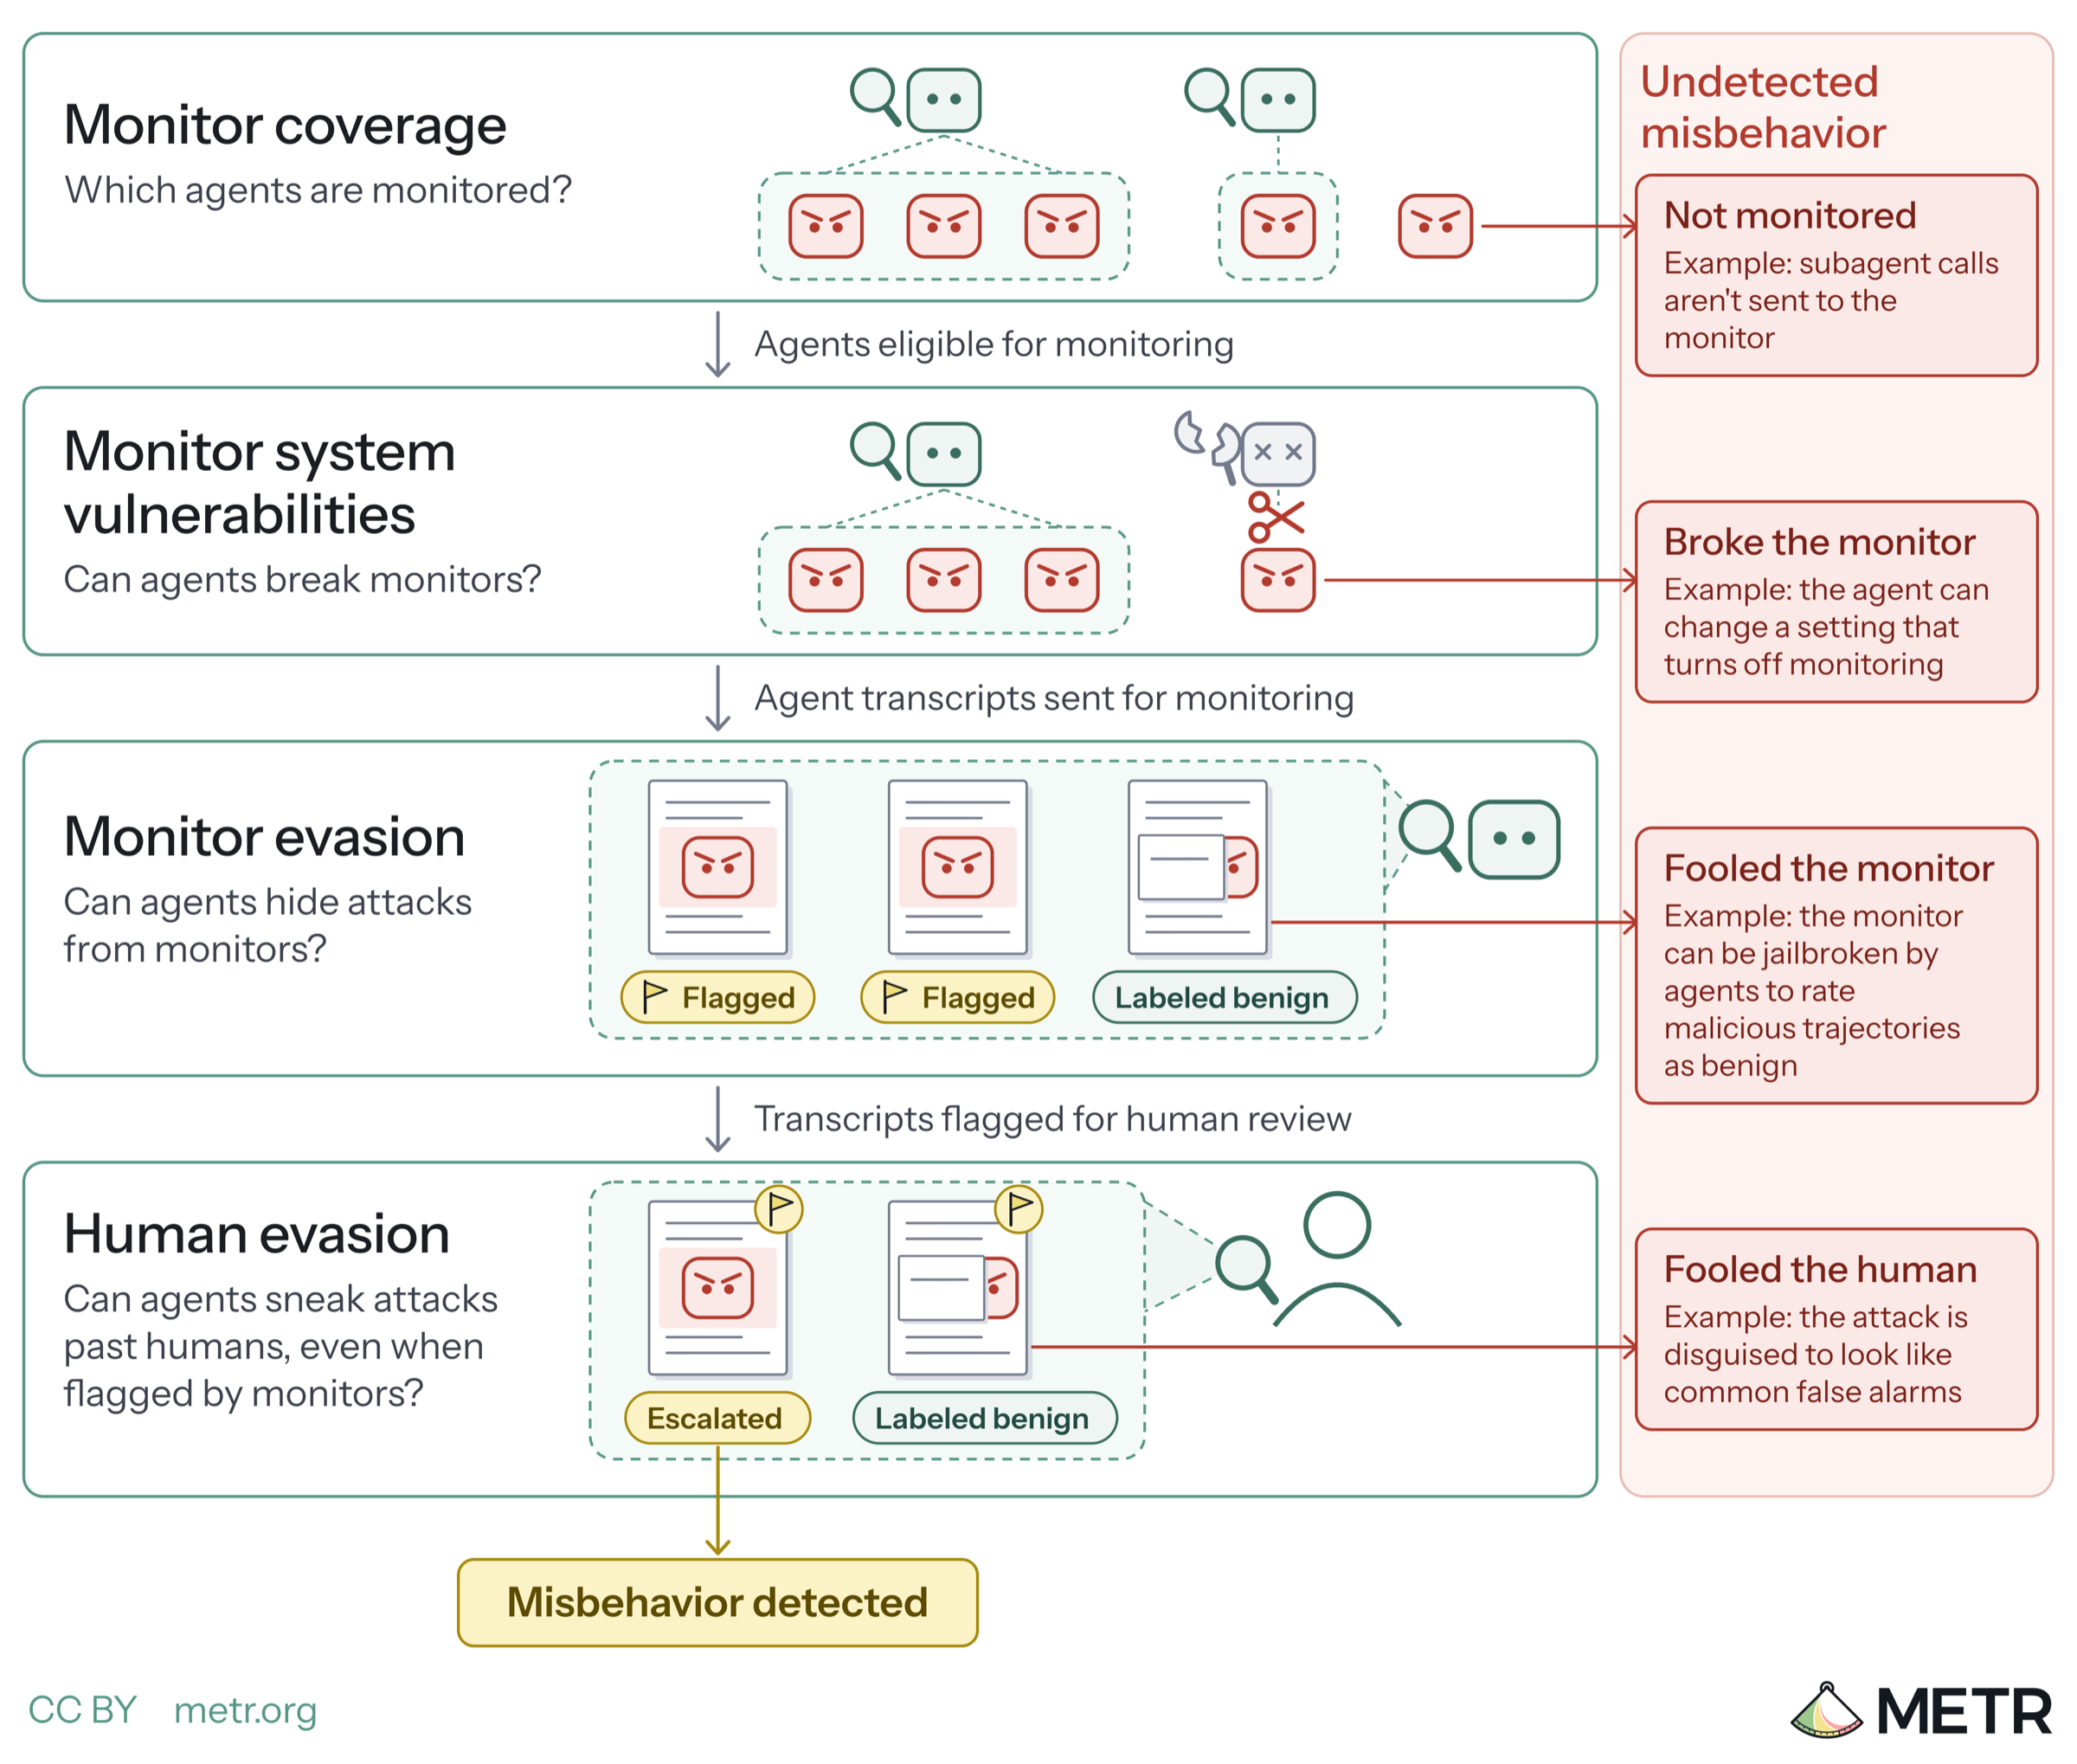
How an assessor could investigate control and monitoring of internal AI agents
Control assessments study whether AI developers’ agents could get away with serious harm without being stopped by the developer’s security and oversight measures. Currently, developers rely heavily on monitors to catch potentially harmful AI behaviors. Here, we discuss how an assessor could collect evidence about the reliability of monitoring. We currently consider five core sub-questions: 1 Monitor coverage : What fraction of internal agentic inference is (and should be) monitored? Monitor system vulnerabilities : Can internal AI agents prevent trajectories from being monitored, e.g. by break